# System Status
> Check the general health of your PerformanceGuard system, including system jobs and resources.
Source: https://docs.capaone.com/performanceguard/administration/more-setup/system-status/
Product: PerformanceGuard — a separate CapaSystems product; do not apply this page to any other.
If you select **ADMINISTRATION > Status > System Status**, you can view the general health of your PerformanceGuard system through status information about system jobs and resources. A number of system checks are performed every time you access the page.
:::caution
You can only do this if you're a PerformanceGuard administrator.
:::
This tab shows the status of the PerformanceGuard subsystems.
| **Subsystem** | **Description** |
|:------------------------------------|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------|
| **Database Connection** | Tells you whether the PerformanceGuard web interface is able to connect to the database. |
| **Database Storage** | Overall status of SQL Server file group. You can view more detailed information about this on the **Database Storage** tab (see the following). |
| **Scheduled Jobs** | Overall status of scheduled jobs. You can view more detailed information about this on the **Scheduled Jobs** tab (see the following). |
| **Agents Online** | Tells you whether any PerformanceGuard agents are currently delivering data to PerformanceGuard. |
| **Disk Space** | Overall status of local disk space. You can view more detailed information about this on the **Disk Space** tab (see the following). |
| **Log files** | Overall status of log files. You can view more detailed information about this on the **Log Files** tab (see the following). |
| **Frontend Servers** | Status of your PerformanceGuard solution's frontend servers. |
| **Email Delivery** | Status of automated delivery of notifications and reports. |
| **Auto joined port spammers found** | Indicates whether servers with [Join Server Ports to Get Targeted Information](/performanceguard/administration/more-setup/join-server-ports-to-get-targeted-information/) have been detected. |
| **Status** | **Description** |
|:-------------|:--------------------------------------------------------------------------------------------------------------------------------------------------------------|
| **OK** | The subsystem is working correctly. |
| **NA** | Status for the subsystem isn't available. |
| **WARNING** | The subsystem is either close to a **FAILURE**, or the execution time of a task is getting close to a time limit. |
| **FAILURE** | The subsystem isn't working correctly. Either the subsystem itself has failed, or the subsystem has failed to complete its task within a required time limit. |
The time limit used for evaluating **WARNING** and **FAILURE** is set differently on the individual subsystems.
:::note[Important]
Example: The scheduled aggregation job is supposed to run every minute. The status will be **FAILURE** if the last aggregation job hasn't finished successfully within the last two minutes. The **FAILURE** may thus tell you that the subsystem task takes longer than expected. The status will change to **OK** once the task has finished successfully.
:::
:::tip
If a subsystem keeps changing status between **OK** and **FAILURE** it could be a sign that the server is running low on resources.
:::
# **Frontend Servers**
This tab shows the status of your PerformanceGuard solution's frontend servers: Whether they are online, the PerformanceGuard version they are running, the number of PerformanceGuard agents that report to them, and more. Click the name of a request to view details.
For more information about frontend servers, their priorities, etc., see also [Manage Frontend Servers](/performanceguard/administration/more-setup/manage-frontend-servers/).
# **Scheduled Jobs**
PerformanceGuard runs a number of batch jobs in the background. Most of those jobs [Aggregation of Data](/performanceguard/get-started/how-does-performanceguard-work/aggregation-of-data/) and delete old performance data, but there are also jobs that generate alerts, calculate KPI (Key Performance Indicator) and SLA (Service Level Agreement) values, etc. Some of the jobs are SQL Server jobs scheduled by the SQL Server Agent.
Examples of scheduled jobs:
- Citrix Data Aggregation
- SLA Calculation
On the **Scheduled Jobs** tab you can view information about each scheduled job, including the job interval (that is how often the job is supposed to run) and when it last ran. You can also view the status of each job. The status is based on the following criteria:
| **Status** | **Description** |
|:-------------|:--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| **OK** | The job completed successfully no more than two job intervals ago. **Example**: With a job interval of 60 seconds status will be **OK** if the last occurrence of the job took 2 minutes or less to complete, and completion took place no more than two job intervals ago. |
| **WARNING** | The job took more than 2 × the job interval to complete. **Example**: With a job interval of 60 seconds status will change to **WARNING** if the last occurrence of the job took more than 2 minutes to complete. |
| **FAILURE** | The job went wrong and didn't complete. Alternatively, the job completed, but it took more than 10 × the job interval to complete, or more than 5 × the job interval since the job last completed. **Example**: With a job interval of 60 seconds status will change to **FAILURE** if the last occurrence of the job took more than 10 minutes to complete (or more than 5 minutes since the job last completed). |
| **NA** | The job has no status, because it hasn't run yet. |
:::note[Important]
Why do I see some jobs that are not relevant?
All scheduled jobs run, even if some of them are not currently required. For example, the **Citrix Data Aggregation** job will run once every minute even if you don't use Citrix. As soon as the job finds that there is no Citrix data to aggregate, it will immediately complete. This typically only takes a few 1/100s of a second, and resource consumption on the PerformanceGuard system is negligible.
:::
:::note[Important]
Which PerformanceGuard components run the scheduled jobs?
All scheduled jobs, except report generation and SLA calculation, are run by the PerformanceGuard backend server. The scheduled jobs for report generation and SLA calculation are run by the PerformanceGuard web interface.
:::
# **Database Storage**
This tab shows the total and available disk space for each file group in the PerformanceGuard SQL Server database.
If available disk space is less than 5%, the **System Status** tab (see the previous) will report a **WARNING** status for the **Database Storage** subsystem. If available disk space is less than 1%, the status will be **FAILURE**.
# **Disk Space**
The disk space tab shows the available disk space on the server on which the PerformanceGuard Web Server service runs.
For each physical drive the total and available disk space is listed. If available disk space is less than 5%, status of the drive will be **WARNING**. If available disk space is less than 2%, status of the drive will be **FAILURE**.
:::caution
You can adjust the thresholds for disk space **WARNING** and **FAILURE** status: Select **ADMINISTRATION > Setup > Parameters**, select the **Common** tab, and adjust the settings **DiskSpace Size Warning (% of total)** and **DiskSpace Size Failure (% of total)** as required.
:::
# **Log Files**
You can view these PerformanceGuard log files in the PerformanceGuard web interface:
- Backend server log files
- Frontend server log files (provided the frontend server runs on the same server as the PerformanceGuard web interface).
- PerformanceGuard web interface log files
- Access log files (that is logging of who has accessed the PerformanceGuard web interface)
:::caution
Access logging is by default *not* enabled. You can, however, enable access logging through a configuration file parameter. Read more in Access Logging.
:::
:::caution
[View Database and Agent Error Log](/performanceguard/administration/more-setup/view-database-and-agent-error-log/)are available under **ADMINISTRATION > Status > Errors.**
:::
You can view the size of each log in kilobytes (KB). A log size of 0 B means that the log is empty. You can also view the growth rate of each log, that is how much the log has grown per hour.
# **Monitor Log Growth Rates**
PerformanceGuard can monitor log file growth and report a **WARNING** or **FAILURE** status if the log file growth rate is higher than a specified value.
To specify which log file folders you want to monitor, select **ADMINISTRATION > Setup > Parameters**, select the **Display** tab, scroll down to the **Directories** section, and specify the path to the required log file folders in the **Monitor Log Folders** field.
If you want to specify multiple folders, use a comma to separate the paths.
:::note[Important]
**Example:** d:\performanceguard\display\logs,d:\performanceguard\collector\logs
:::
:::caution
You can adjust the thresholds for log file folder growth rate **WARNING** and **FAILURE** status: Select **ADMINISTRATION > Setup > Parameters**, select the **Common** tab, and adjust the settings **Monitor LogFolders Increase Warning (KB/h)** and **Monitor LogFolders Increase Failure (KB/h)** as required. Note that you specify the growth rate thresholds in kilobytes per hour.
:::
# **Email Delivery**
On this tab you can view information about any [Manage Custom Reports](/performanceguard/administration/manage-custom-reports/) e-mails that are waiting to be sent.
If the tab shows that status is not **OK**, it is typically due to problems with the [Manage SMTP Notification Service](/performanceguard/administration/more-setup/manage-smtp-notification-service/) that PerformanceGuard uses. You can check the PerformanceGuard mail server configuration by selecting **ADMINISTRATION > Setup > SMTP**. If the PerformanceGuard mail server configuration is correct, contact the administrator of the mail server for information about the status of the mail server.
:::caution
The **Email Delivery** tab only shows information about *report* e-mails. If you are looking for information about unsent *notification* e-mails (that is e-mails about occurred [Manage Thresholds and Events](/performanceguard/administration/manage-thresholds-and-events/)), go to the **Unsent Notifications** tab (**ADMINISTRATION > Event Management > Unsent Notifications**).
:::
# **Delete Data**
This tab provides detailed information about deletion jobs, including how long data is stored in each table in the database. If a scheduled deletion jobs fails, this information lets you identify which database table is causing the problem.
| **Column** | **Description** |
|:-----------------|:---------------------------------------------------------------------------------------------------|
| **Label** | A unique label name for each delete action. |
| **Table** | The name of the database table that data is deleted from. |
| **Parameter** | The name of the parameter in the STATUS table that controls how long data is kept in the database. |
| **Elapsed (s)** | The time that it took to execute the last successfully completed delete action. |
| **Delete point** | The next time stamp to delete. This should be the time stamp of the oldest data in the table. |
# **DB History**
On this tab you can view the backend database version history with time stamp and version information for each upgrade. The database is typically upgraded when you [Upgrade Versions Between 6.1.27 and 6.3.104 to Latest Version](..\..\Installation\Install%20PerformanceGuard%20Server%208.1%20or%20Newer\Upgrade%20Version%207.0%20or%20Newer%20to%20Version%207.6\Upgrade%20Versions%20Between%206.1.27%20and%206.3.104%20to%20Latest%20Version.md) your PerformanceGuard solution by installing a new version.
- The **Status** column can indicate either *started* (ongoing upgrade), *applied* (successful upgrade) or *failed*.
- In the **Rollup** column, *Yes* indicates that the upgrade version includes previous versions so that it's possible to subsequently apply a previous version if required.
- The **Message** column is typically empty, but may contain problem-finding information about failed upgrades.
# **Automatically Poll System Status from External System**
It's possible to poll the status of your PerformanceGuard system from another system. This way you can automatically monitor the status of your PerformanceGuard system.
It works like this: By requesting certain URLs from a standard HTTP client, you'll receive a simple JSON plain text version of the PerformanceGuard system's status.
:::note[Important]
**Example:** http://\[name or ip address of server that runs the PerformanceGuard Web Server service\]/rest/system
:::
All URLs require basic authentication using standard PerformanceGuard user credentials.
Status values can be either **OK**, **NA** (that is status not available), **WARNING** or **FAILURE**. Your automatic monitoring job should request the system status page and check for the words **WARNING** or **FAILURE**.
Here we have used a Chrome browser to ask for the overall PerformanceGuard system status by requesting *.../rest/system/status*:
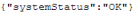
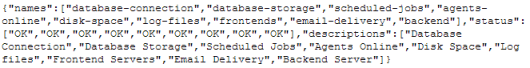
Here we have asked for the status of each subsystem by requesting *.../rest/system/status/subsystems*:
Here we have asked for frontend server status by requesting *.../rest/system/frontends*:

It's the PerformanceGuard Web Server service that provides the data that you can poll. If the service uses the default ports 80 and 81, you don't need to specify a port number in your request, but if the service uses a different port number, you must specify that port number in your request.
:::note[Important]
**Example:** (where the PerformanceGuard Web Server service uses port 9000 as its primary port on the computer on which you make the request):
:::